Remembering Experience vs. Retraining Models: Two Distinct Processes in AI
This article examines the fundamental differences between experience accumulation and model training in enterprise AI systems, highlighting how knowledge updates, memory retention, and parameter optimization require distinct system architectures and maintenance approaches.
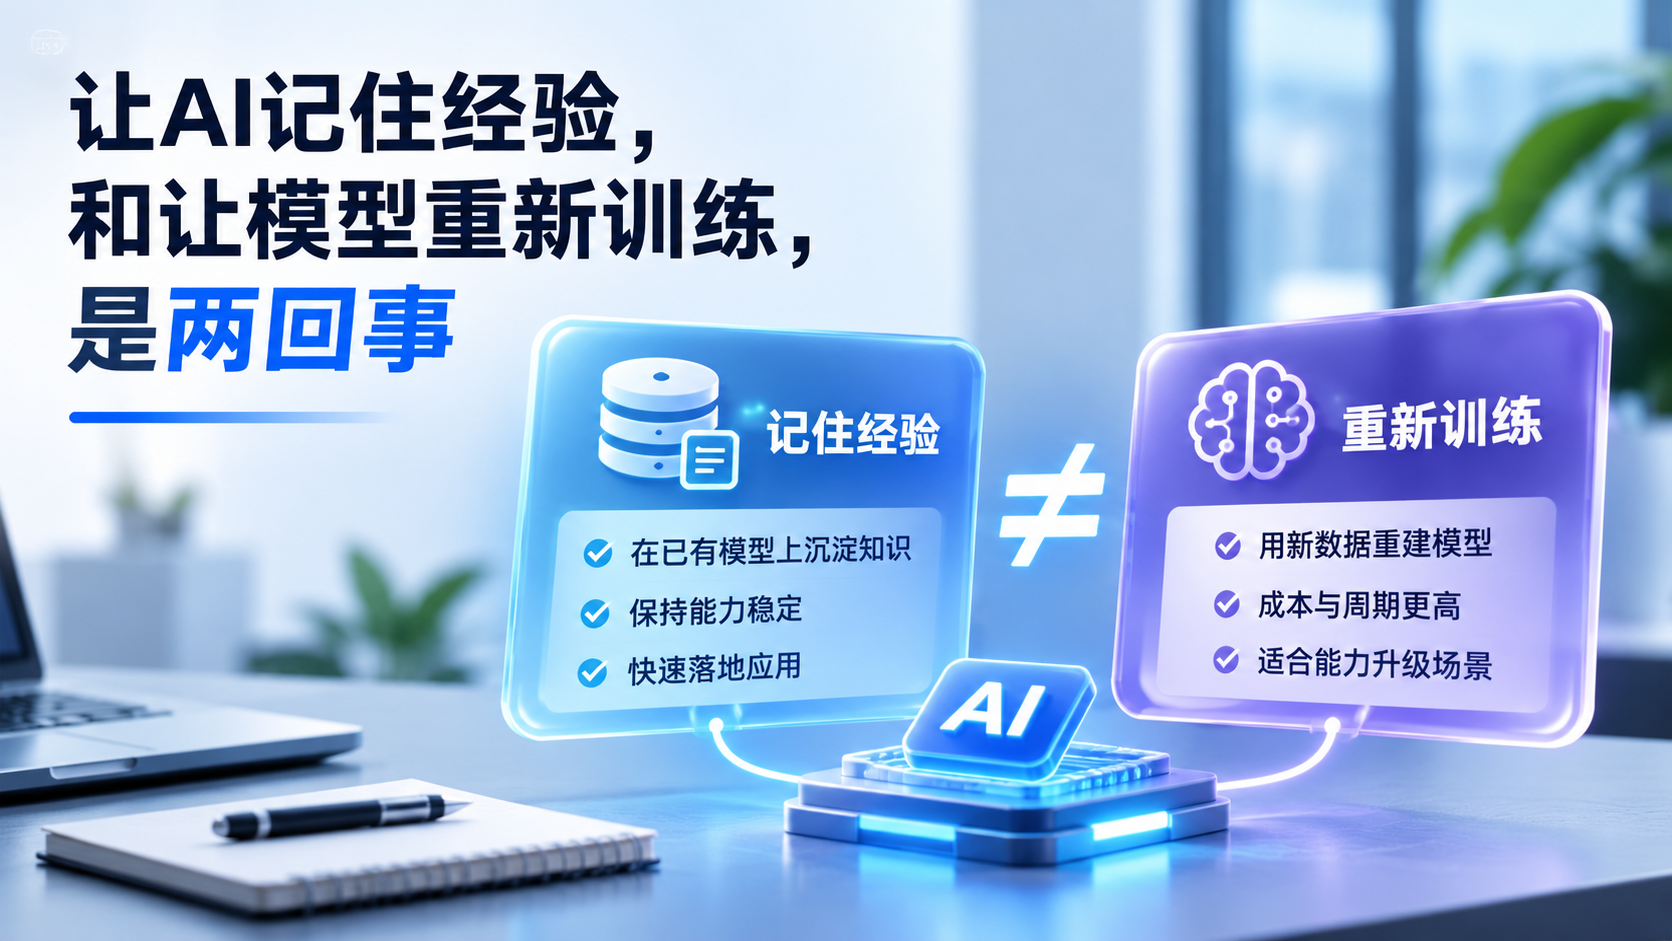
Remembering Experience vs. Retraining Models: Two Distinct Processes in AI
By Hou Yanjun
When an enterprise deploys an AI system that gradually incorporates new cases, employee feedback, and operational experience, its responses do become more business-aligned over time. But does this constitute "getting smarter with use"?
Superficially, yes. But if we're discussing "automatic model training," we must examine what actually occurs. Often, model parameters remain unchanged—what evolves are the accessible references, contextual inputs, and execution rules governing tasks.
This distinction critically impacts system architecture and maintenance strategies. Assuming continuous usage alone enables AI to organically absorb experience—reducing errors while maintaining updated knowledge—often leads to disappointment. Purposeful design is required for data storage protocols, value assessment for retention, and retrieval mechanisms.
First, knowledge updates. When revised internal policies enter the knowledge base, the system retrieves relevant clauses during employee queries, feeding both the policy text and question to the model (Retrieval-Augmented Generation, or RAG). This leverages new information without model retraining—ideal for dynamic product details, regulations, and operational requirements where version control and source attribution matter.
However, document uploads don't guarantee effective updates. Teams must verify: Are legacy versions deactivated? Is new content properly parsed? Does retrieval locate correct clauses? Even with accurate retrieval, models may overlook conditions or misinterpret content. Troubleshooting requires examining data, retrieval, and generation layers sequentially—not defaulting to "model capability" critiques.
Memory systems add complexity by utilizing historical interactions beyond reference searches.
Current dialogue context feeds directly into models, while cross-conversation retention requires external storage for later recall. This enables information persistence without parameter changes. But indiscriminate chat logging only achieves storage—not intelligence. Systems must discern relevant records from obsolete ones.
For example, if a user initially mentions market expansion plans later canceled, uncritical record accumulation might still generate market-entry suggestions. Proper implementation prioritizes current status while preserving decision trails for audit purposes—otherwise stored statements remain disconnected facts.
Experience codification proves more challenging than fact recording, as successful outcomes don't equate to universal rules.
Solution acceptance often depends on contextual factors like budget constraints, client relationships, or timelines. Summarizing merely as "this approach worked" while omitting conditions risks inappropriate replication. Uncontested answers shouldn't imply correctness.
Developing our digital expert distillation system required capturing not just expert knowledge, but their decision rationale, circumstance-dependent adjustments, and competency boundaries. Here, "distillation" means experience extraction—not model training. For instance, when experts evaluate problems by assessing specific criteria before eliminating options, we formalize this process as reference cases, retrieval materials, or task rules. Missing premises or execution failures still cause deviations from expert judgment.
This underscores the need for post-extraction validation. Comprehensive documentation and operational adherence are separate concerns requiring distinct verification.
Model training typically updates parameters via datasets and optimization to alter output behavior. "Training" needn't mean full model rebuilding: fine-tuning may adjust original parameters or train supplementary adapters while freezing base model parameters. Parameter change—not base model replacement—defines training.
This fundamentally differs from storing cases in databases for model reference. Both approaches can coexist—neither is universally superior nor mutually exclusive.
Enterprises should align solutions with specific needs.
Frequently updated policies requiring source citations benefit most from robust versioning and retrieval systems. For consistent task execution in stable domains, fine-tuning may help—but still demands data preparation and post-training validation.
Training cannot replace document updates or access controls. A fine-tuned model won't automatically recognize recent policy changes or manage information permissions.
Thus, "getting smarter" requires transparent evolution tracking: new knowledge additions, record corrections, validated experience accumulation, or parameter updates.
Precise tracking aids troubleshooting: Check versioning for unused policies; examine memory updates for obsolete plan references; verify condition preservation for misapplied experiences. Different issues demand tailored solutions—not blanket model replacements.
Validation should mirror these dimensions: Do policy updates reflect in related queries? Do rescinded decisions stop influencing suggestions? Do corrected cases prevent recurring errors in similar tasks? Comparative performance assessments across representative tasks prove more meaningful than single-response evaluations.
Enterprises needn't train proprietary models to accumulate knowledge. But merely storing more data or generating summaries without verifying accuracy, timeliness, and retrievability won't yield reliable systems—regardless of usage duration.
Technical References
[1] Anthropic: Effective context engineering for AI agents. Explains context management, compression, and external memory storage for subsequent recall.
[2] Hugging Face PEFT Documentation: LoRA. Details low-rank adaptation methods demonstrating parameter training while preserving base model parameters.